writing
When Deep Neural Nets Fail
Oct 2022
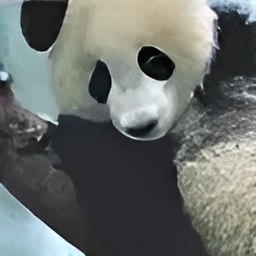
A Panda that is predicted as a Gibbon with 99.3% confidence
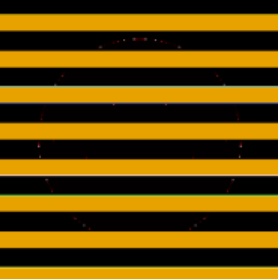
A Yellow/Black stripe is predicted as ‘school bus’ with ≈99.12% confidence 2
Adversarial Examples are imperceptible perturbations of natural inputs that induce erroneous predictions. Their corollary: Fooling Images 2 — unnatural inputs that trigger high-confidence predictions yet remain unrecognizable to humans.
These two phenomena expose three failures in simple Deep Neural Networks (DNNs): over-confidence, discriminatory narrow-sightedness, and lack of intentionality.
-
Over-confidence - A human would give an out-of-sample input low confidence. The model cannot detect that its frame of reference is incoherent, so it won’t flag the answer as uncertain.
-
Discriminatory Narrow-sightedness - Humans make high-level inferences, partly because we discard much of our visual input; three times per second we go blind from Saccades and don’t notice.
- Deep Neural Nets use no such tricks. They dredge through data seeking any pattern with discriminatory power — even features utterly inhuman and unintended. These non-robust features predict well but prove brittle for broader object recognition.
-
Intentionality Failure - These examples aren’t model failures. They’re challenges of intention. Restricting the model to human-interpretable features isn’t the answer — we’d lose valuable, perhaps inhuman, features.
Neural Networks pay far more attention to texture and color than humans do when classifying.
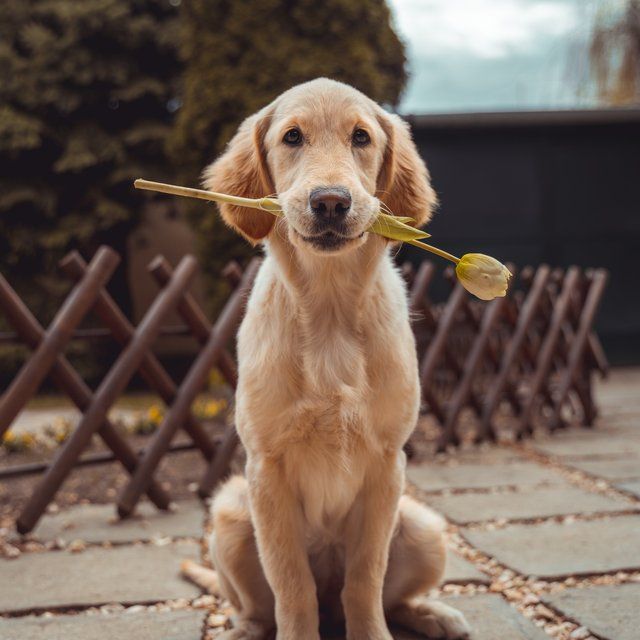
Dogs are photographed outdoors, at a distance, with zoom lens bokeh. The model learns these texture cues alongside the animal. Photo by Richard Brutyo.
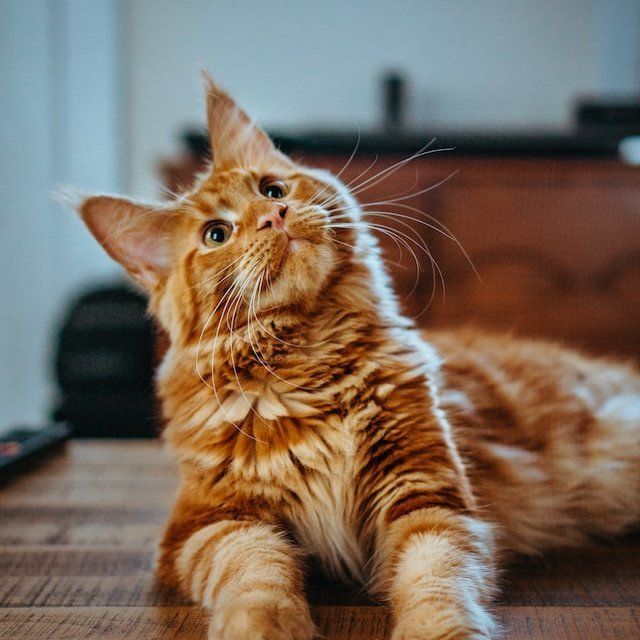
Cats are photographed indoors, close up, on soft surfaces. Different subject, different lens artifacts, different background textures. Photo by Amber Kipp.
The “Fooling Image” reveals a more fundamental issue:
- A Lack of Sufficiency - DNNs assume all discriminatory features are sufficient. If the only images with black and yellow stripes are school buses, that becomes a sufficient feature. A human would treat it as a mere indicator, not a conclusion.
Footnotes
-
Adversarial examples are not bugs, they are features.
Ilyas, Andrew, Shibani Santurkar, Dimitris Tsipras, Logan Engstrom, Brandon Tran, and Aleksander Madry. Advances in neural information processing systems 32 (2019). ↩ -
Deep neural networks are easily fooled: High confidence predictions for unrecognizable images.
Nguyen, Anh, Jason Yosinski, and Jeff Clune. Proceedings of the IEEE conference on computer vision and pattern recognition. 2015. ↩ ↩2